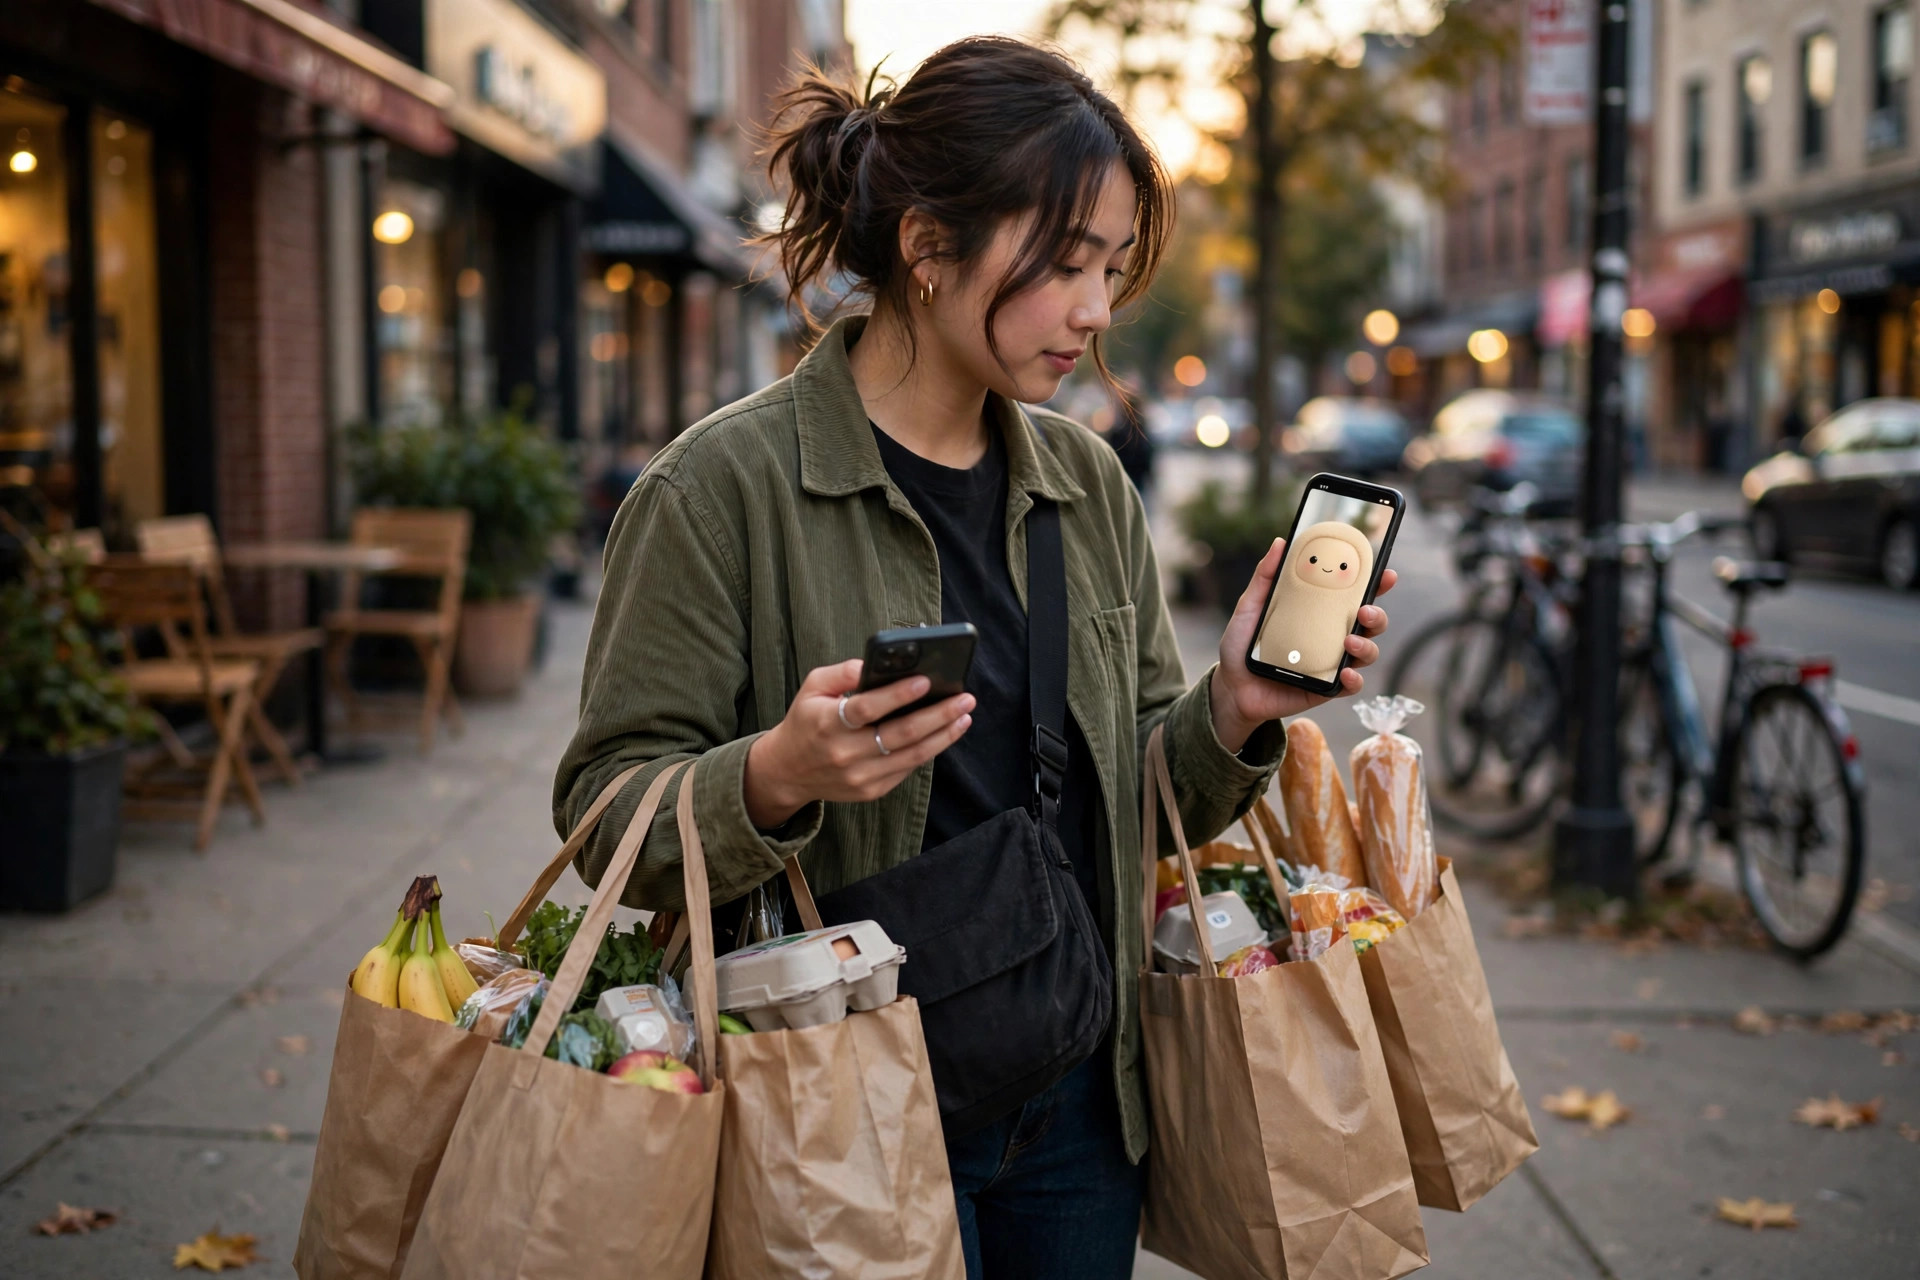
Imagine it from the outside. A person walks down a street with both hands full, groceries in one arm and a phone in the other, talking to a small furry face on the screen. Nobody else can see the face or hear the other side of the conversation, which is the whole strangeness of it: a two-way exchange with only one visible participant, conducted in public, at full volume, with a machine. Nobody else is there.
That is the scene Meta shipped on November 5, 2026, when Muse gained a live voice and an expressive avatar in the United States. You tap the phone icon in the top-right corner of the Muse app, on mobile, on the web, or on a Mac, and you start talking. Muse talks back, right away, and you can interrupt it mid-sentence the way you would interrupt a person. While you keep talking, it keeps working in the background, booking and buying and sending on your behalf. Meta previewed all of this at Connect on September 23 and shipped it six weeks later, which by the standards of this product counts as keeping a promise.
Voice is not a new way to type. It is a different relationship with the machine, and the relationship is the story. It listens. It acts. Typing puts a screen between you and the agent. You watch it work, you read what it did, you tap to approve. Voice removes the screen at exactly the moment the agent is doing the most consequential things it can do, which is the design tension this whole launch turns on.
What actually arrived
Conversations run in real time, and hundreds of voices are available, changeable whenever you want. Meta's examples for the range are the energy of a New Yorker and the flair of a pirate, which tells you the catalog is built for mood rather than realism, though Meta has published no list of the voices, no language coverage, and no word on whether any of them are licensed from real people.
You get three ways to look at the thing you are talking to: voice only, with no face at all; the avatar sitting beside your conversation; or full screen, face to face, the way you would hold a video call. In every mode with the avatar visible, it uses what Meta calls subtle expressions and gestures that match the tone of the conversation, and it reacts while you are still speaking, so you can tell it is following along. Meta's suggested uses are domestic and practical rather than grand: brainstorming, trip planning, rehearsing for a job interview or a presentation or a pitch.
Two demo clips on the announcement page show what Meta thinks this looks like in practice. In one, a user asks, "Can we role play my interview, then email the recruiter to confirm the date?" Muse answers, "Let's do it! I'll play the hiring manager." In the other, a cooking exchange, a user asks for recipe ideas for an "Italian queso" and Muse suggests "Queso e Pepe," which it describes as a Texas spin on the dish. Neither demo is spectacular, and that is the point. Voice mode is built for the half-formed request, the idea you start out loud and let the agent finish.
The arithmetic under the face
Behind the voice and the avatar sit two systems Meta names in the announcement and explains in a research post from September 23, "Bringing Your Muse to Life." Muse Realtime Voice produces a stream of speech tokens that carry both what is said and how it is delivered. Muse Realtime Avatar reads the same token stream, which is how the lip movement and the facial expression stay in step with the voice. The avatar model is an audio-driven diffusion transformer. It takes three inputs, the speech tokens, a reference image that can be a portrait or an illustration or an object, and a rolling window of video it has just generated, and it produces video in short chunks, one after another.
Speed came from distillation, and the numbers are unusually honest for a product launch. The original teacher model needed 40 diffusion steps with three guidance passes each, or 120 model evaluations per video chunk, while the production student needs two, a 60-fold reduction, and Meta says the smaller model closely preserves the teacher's quality. The headline figure is latency: about 870 milliseconds from the end of your turn to the first byte of synchronized voice and video. Video renders at 448 by 768 pixels in portrait orientation, at 25 frames per second, and generated video carries Meta Video Seal, the company's invisible watermark.
Here is the piece of arithmetic nobody at Meta has volunteered, and it explains more about this launch than any demo clip. After quantization, one Nvidia GB200 chip runs 12 concurrent real-time avatar sessions. Sensor Tower put Muse at 2.5 million US daily active users on October 20. If 1 percent of those people were talking to an avatar at the same moment, 25,000 users, that would occupy about 2,083 GB200 chips running nothing but faces. At 10 percent concurrency, about 20,833 chips. Zuckerberg said on the October 21 earnings call that Muse had not launched globally because it is expensive in compute to run. Now you can see the shape of the expense. A face that reacts in under a second is a small data center, per conversation, and the US-only rollout is the receipt, because a feature that reserves a twelfth of a flagship AI chip for every person using it cannot be handed to the whole world at once, no matter how many people ask for it, and the countries still waiting are waiting on hardware, not on paperwork.
A video chat where only one side has a camera
Now the face itself. The default avatar is a cute animated character nicknamed Jolly. Alexandr Wang, Meta's chief AI officer, announced the rollout on X with a demo in which his own Muse appears as a fluffy white dog. Users can restyle the avatar into something that looks like a person, an animal, or another character, according to TechCrunch's November 5 report. Meta's own post does not say whether you can design your own avatar or pick a human-looking one, which is a meaningful silence, because the answer changes what the product is.
Look closer at the demo clips and you notice what the face is made of. A furry, cream-coloured creature. A baseball cap with an Italian flag in one clip. A cowboy hat in the other. It is charming, and the charm is doing legal work. Charming on purpose.
On October 28, 2026, New York Governor Kathy Hochul signed a law barring operators from offering minors 12 features classed as unsafe, including outputs suggesting the system is human, and the law's definition explicitly covers systems that interact through writing or sound. It takes effect January 1, 2027. California's SB 243, signed in October 2025, already requires a notice where a reasonable person could be misled into thinking a chatbot is human. Muse is restricted to users 18 and over, and its demo avatars are plainly not human, which limits the overlap with both laws. Whether Muse counts as a companion product under either law has not been tested, but the design choice is visible on the screen: a creature in a cowboy hat does not invite the confusion a photorealistic human face would. Cuteness is the alibi. Non-human is the compliance strategy.
There is a second asymmetry the word "video chat" hides. TechCrunch states it plainly: Muse does not see you. It hears you and reacts based on the conversation. You are looking at a face that performs attentiveness, nodding and reacting while you talk, and the performance is generated entirely from your audio. Nothing on the other end is watching your expression. That is not a defect. It is the product. But it is worth naming, because the feeling of being seen is exactly what a reacting face sells, and the face is selling a feeling it cannot deliver.
What Meta did not say
Three gaps stand out once the announcement is read against what Muse already promises, against the small-business post from September that said nothing publishes or spends without approval, and against the launch-day commitment that the data inside your agent's private machine stays out of the advertising business.
First, approvals. Meta's September 29 post on Muse for small business said nothing publishes, sends, or spends without the user's approval. That is the core safety promise of an agent that acts on your behalf. The voice launch demo's own example is an email to a recruiter, sent mid-conversation. Meta's post does not explain how approvals work when you are speaking rather than tapping. A spoken yes is presumably the approval, but Meta never says so, and there is no documented voice-mode approval flow. Voice is precisely the mode where you are not looking at a screen, which is precisely when an approval deserves the most care, and the launch says nothing about it at all.
Second, recordings. The post does not say whether voice audio is stored, for how long, whether transcripts are kept, or whether recordings are used to train Meta's models. At launch, Meta said conversations and data inside each person's Muse Secure VM are not shared with its ad systems, and that people can opt out of having their interactions used for model training. The voice post neither repeats that commitment nor says whether spoken conversations fall under it. There is a precedent worth knowing. In October 2025, Meta said that from December 16, 2025, people's interactions with its AI features would be used to personalize content and ads, and it explicitly included voice chats alongside text exchanges. That policy covered Meta AI, not Muse. On the October 21 earnings call, Zuckerberg said people who want Muse to improve the personalization of their content and ads across Meta would be able to connect those experiences, without explaining what data would cross. The direction of travel is not fixed, but it is not fenced off either, and the launch post leaves the fence unbuilt, which means the only thing standing between your spoken conversations and Meta's advertising business is a launch-day promise that the newest announcement did not bother to repeat.
Third, geography and surface. Voice is US-only "to start," though Muse itself was available in the US and Canada by September 29, and it has since reached Japan, Singapore, and Mexico. No date has been given for any of them. WhatsApp, where Muse has been reachable since launch day, is not mentioned in the voice post at all. The post also does not say whether voice, the avatar, or particular voices are limited to a paid tier, though secondary reporting says no paid plan is needed for voice. Phone calls to businesses, a related voice feature that arrived November 12, are paid subscribers only, according to TechCrunch's reporting that week, which suggests the free tier is not a permanent guarantee for everything with a voice attached.
The other side, at full strength
None of that erases what is genuinely new here, and it would be dishonest to pretend otherwise. Every other way of talking to Muse starts with friction: unlock the phone, open the app, describe the situation in words. Voice removes the phone from the interaction at the moment your hands are full, which is the moment an agent is most useful and least used. A long conversation in which the agent keeps working while you keep talking is not a voice assistant with better diction, and it is not a phone call with a smarter menu, either. It is a different division of labor, one where you supply intent in fragments and the agent supplies the follow-through, and the demo clips, for all their modesty, show the shape of it: a half-formed idea, picked up mid-sentence, carried to completion while you are still deciding what you meant, with no screen in between to show you what it did.
Consider the alternative design, too. Meta could have shipped a photorealistic human face, or no face at all, and either choice would have been easier to defend. A human face would have invited the companion-chatbot laws and the arguments about deception that follow them. No face would have kept voice mode feeling like a phone call to a call center. The furry creature in the cowboy hat is a middle path, and the middle path is doing real work: it makes the agent feel present without pretending to be a person, it gives you something to look at while you talk, and it keeps the legal exposure at arm's length. That is a design decision, not a decoration, and it deserves to be judged as one.
There is also a cost to the speed that deserves a hearing, stated as a hypothesis rather than a finding. The 870-millisecond answer comes from a student model distilled 60-fold from its teacher, and a comment on Meta's official November 9 Facebook post says voice answers feel "a bit less sharp" than typed ones. One comment proves nothing, and no independent benchmark of voice-mode answer quality exists yet. But the mechanism is plausible: when you compress a model that far for latency, something has to give, and depth is the usual casualty. If you need the sharpest answer Muse can give, type it. If you need an answer while your hands are full, talk. That is the trade. It is a reasonable one, as long as nobody pretends it is not a trade.
What I could not verify
I have not used Muse Voice myself, so every capability claim here comes from Meta's announcement, its research post, and same-day reporting, not from a hands-on test, and that limitation matters more for a voice product than for a text one, because the qualities that decide whether you will actually use it, the naturalness of the pauses, the way it handles being interrupted, the voice you end up living with, are exactly the qualities no announcement can describe. Meta has not published which languages voice supports, how long a session can run, or whether the free tier covers voice by name. No date exists for the rollout reaching Canada, Japan, Singapore, or Mexico, and about 5 percent of sampled recent Google Play reviews report that live voice conversation is unavailable on their account, according to a November 9 count by the review tracker ParseMyApp, so "rolling out" and "available to everyone" are not the same claim. The GPU arithmetic in this article is my own calculation from Meta's published figures and Sensor Tower's user counts, not a number Meta published, and it assumes avatar mode; voice-only sessions cost far less. The "less sharp" observation is a single user comment, not a measured result. And the claim that the non-human avatar is a deliberate legal strategy is my reading of the design against two statutes, not a statement Meta has made.
What to do before your first voice call
First, try it in voice-only mode before you turn the avatar on, because the face changes how the conversation feels and you should know what the voice alone is worth. Second, rehearse something low-stakes, a brainstorm or a trip plan, before you hand it a task that sends or spends anything, and watch how it asks for approval out loud, since Meta has not documented that flow. Third, decide in advance what you will never approve by voice: money, messages to people who matter, anything you would want to read before it goes out. Say that rule to Muse in text first, where you can see it land. Fourth, check whether the feature has actually reached your account before you plan around it, because the rollout is uneven and the app will not warn you in advance. Fifth, if you are outside the United States, do not wait by the phone. No date exists for your country, and the compute math in this article is the reason why.
Muse learned to talk in November, and the talking works, which is the least surprising sentence in this article, because Meta has been rehearsing this exact moment since Connect, when it first promised a conversation that keeps going while the work gets done in the background. The interesting part is everything around the talking: a face that performs listening without seeing, a voice you can redesign by describing it, a creature in a cowboy hat standing between the product and the companion-chatbot laws, and a silence where the answers about recordings and approvals should be. Talk to it, and enjoy it, but keep your eyes open while you do, because the face is watching you in the only way it can, which is not at all, and the voice that answers you in under a second is the product of a machine that was distilled sixty-fold to fit the moment, not the machine that would have taken its time. The face cannot see you.